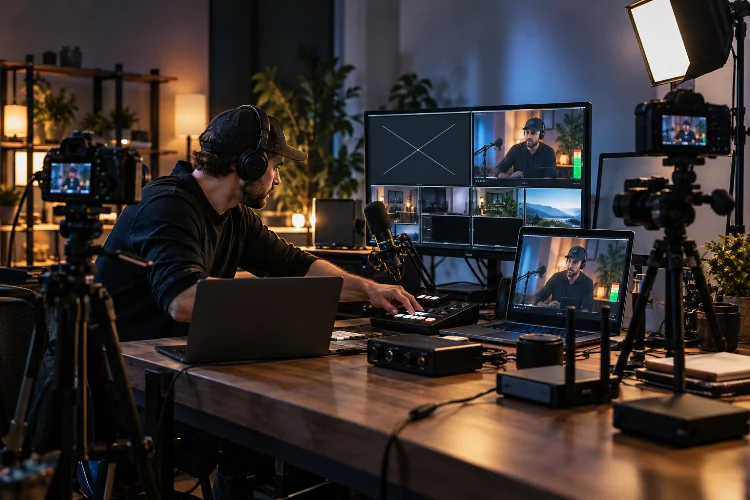
Imagine you’re hosting an important gaming livestream. Your audience is growing, the gameplay is getting intense, and everything seems to be running perfectly. Suddenly, your internet connection drops, OBS freezes, or your microphone stops working.
Within seconds, your carefully planned broadcast turns into a technical nightmare.
For streamers, esports organizers, and live content creators, production failures aren’t just annoying. They can interrupt audience engagement, damage viewer confidence, and potentially affect sponsorship commitments or important live events.
That’s why managing stream production failures with redundant workflows should be part of every serious broadcasting strategy.
Redundancy simply means having alternative systems ready when your primary equipment, connection, or software fails.
Instead of relying entirely on one computer, one internet connection, or one recording method, you design your production setup to handle unexpected problems.
The good news? Building a reliable livestream doesn’t necessarily require an expensive television studio.
With thoughtful planning, practical backup solutions, and regular testing, creators can reduce downtime while maintaining professional broadcast quality.
This guide explains how to identify production risks, develop reliable failover systems, protect recordings, and recover quickly when livestreaming technology doesn’t cooperate.
1. Identify Critical Failure Points in Your Streaming Workflow
Before purchasing backup equipment, you need to understand where your current production system is vulnerable.
Every livestream depends on several interconnected components. When one essential component fails, the entire broadcast may be affected.
Map Your Complete Production Pipeline
A typical gaming livestream involves gameplay capture, audio input, video processing, encoding, internet transmission, and delivery through a streaming platform.
The workflow generally looks like this:
Game or Camera → Capture and Audio Sources → Streaming Software → Encoder → Internet Connection → Streaming Platform → Viewers
Each stage introduces a potential point of failure.
For example, your gaming computer might work perfectly while a USB capture card disconnects unexpectedly.
Alternatively, OBS may continue encoding normally even though your internet service provider experiences an outage.
Understanding these differences helps you select the appropriate backup solution.
A secondary microphone won’t solve an internet problem, just as a backup router won’t prevent software crashes.
Identify Single Points of Failure
A single point of failure is any component whose malfunction can interrupt an essential part of your production.
A basic streaming setup might depend entirely on one computer, one microphone, one router, and one internet connection.
That simplicity makes it affordable but also vulnerable.
Start by asking what would happen if each component suddenly stopped functioning.
Could you continue streaming without your primary camera? What happens if your encoder crashes? Would a brief power outage disconnect every device?
These questions reveal which systems deserve redundancy.
For a casual streamer, losing a webcam might be inconvenient but manageable. For an esports tournament broadcasting a championship match, losing the main program feed could be a critical failure.
Prioritize Risks by Impact
Not every problem deserves an expensive backup.
Evaluate failures according to their likelihood, potential consequences, and recovery difficulty.
For example, temporary internet instability may be more common than complete encoder hardware failure.
However, a malfunctioning production computer during a sponsored event could produce significantly greater disruption.
Prioritize systems that protect the broadcast’s most important functions.
This risk-based approach creates better reliabilty without wasting money on unnecessary equipment.
2. Build Redundant Internet Connections and Network Failover
Internet connectivity is one of the most important parts of livestream production.
Even powerful computers and professional cameras cannot maintain a public broadcast without a functioning transmission path.
A reliable network strategy should account for bandwidth limitations, routing problems, and unexpected service interruptions.
Use Independent Internet Connections
One practical approach is maintaining two internet connections.
Your primary connection might use fiber broadband, while a secondary connection uses another provider or a cellular network.
The important word is independent.
Two connections from the same provider may share infrastructure, meaning a single outage could affect both services.
Where possible, choose connections with different providers, access technologies, or physical routes.
For example, fiber broadband combined with a 5G cellular connection may provide more useful redundancy than two connections dependent on the same local equipment.
However, cellular performance can vary with coverage, congestion, and data limits.
Test your backup connection using the actual streaming bitrate before relying on it.
Configure Automatic or Manual Network Failover
Some dual-WAN routers can monitor multiple internet connections and switch traffic when the preferred connection becomes unavailable.
This can reduce manual intervention during outages.
However, switching connections may interrupt an existing livestream session because the public IP address and network path can change.
OBS may need to reconnect, and the streaming platform may not preserve the session seamlessly.
True connection bonding, which combines multiple connections through compatible software or services, is different from ordinary router failover.
Bonding can improve resilience when supported, but it introduces additional equipment, subscriptions, and possible latency.
For smaller creators, a tested manual backup connection may be sufficient.
Professional productions may justify more advanced managed connectivity systems.
Use OBS Connection Recovery Features
OBS Studio provides several features for troubleshooting streaming interruptions.
Its network troubleshooting documentation recommends investigating bitrate, ingest server selection, network equipment, and connection stability.
OBS also supports automatic reconnection settings.
Enabling reconnection can help the software resume sending video after temporary connectivity problems.
However, reconnection alone isn’t network redundancy.
If your only internet connection is unavailable, repeatedly reconnecting won’t restore service.
Think of automatic reconnection as a recovery mechanism that works alongside an independent backup network.
3. Protect Your Encoder and Video Production System
The encoder is responsible for converting your video and audio into a format suitable for livestream transmission.
When encoding software or hardware fails, the platform may stop receiving your broadcast.
This makes encoder reliability particularly important during professional productions.
Prepare a Backup Streaming Configuration
For smaller creators, a secondary OBS configuration can provide a practical recovery option.
OBS allows users to create Profiles and Scene Collections.
Profiles store many streaming and output settings, while Scene Collections preserve scenes and their associated sources.
You can create a simplified emergency configuration with fewer overlays, lighter graphics, and less demanding encoding settings.
For example, your normal broadcast might include animated alerts, multiple cameras, and complex transitions.
Your backup scene collection could contain only the gameplay capture, microphone, and a simple visual layout.
If a performance issue affects the primary configuration, switching to a lighter setup may help.
However, configurations are only useful when the underlying software and computer remain functional.
A complete system crash requires a seperate recovery solution.
Consider Dual-Encoder Production
Larger productions may benefit from two independent encoders.
The primary encoder handles normal broadcasting, while a secondary encoder remains ready to provide an alternative feed.
These can be dedicated hardware units or independent computers running compatible encoding software.
The important requirement is avoiding shared failure points.
Two software encoders running on the same malfunctioning computer don’t provide meaningful protection against a full system failure.
Likewise, two encoders using the same failing power supply or network switch remain vulnerable.
A properly designed system separates critical components wherever practical.
Understand Automatic Input Failover
Professional streaming infrastructure can support automatic switching between primary and backup video inputs.
For example, AWS Elemental MediaLive offers automatic input failover for supported input configurations.
The service can detect certain input problems, including source loss, black video, and audio silence, then switch to an available standby input.
AWS also distinguishes input redundancy from pipeline redundancy.
Input redundancy protects against failures before the processing pipeline, while pipeline redundancy protects the processing infrastructure itself.
These capabilities require supported configurations and may introduce additional costs.
They aren’t equivalent to simply sending two feeds to the same Twitch or YouTube stream key.
Never assume a streaming platform accepts simultaneous redundant encoders unless its documentation explicitly supports that arrangement.
For smaller channels, a prepared secondary encoder with a tested manual transition procedure may be more realistic.
4. Create Backup Audio, Video Capture, and Power Systems
Internet and encoder redundancy receive plenty of attention, but other production components can fail just as easily.
Audio interfaces, microphones, capture cards, cameras, and power equipment deserve their own recovery plans.
Build a Practical Audio Backup Path
Audio problems can make a livestream difficult to follow even when the video remains perfectly clear.
A USB microphone may disconnect, an audio interface might lose power, or a software update could change the selected input device.
A simple backup might be a headset microphone that can be activated quickly.
Professional productions may use secondary microphones, independent audio interfaces, or backup mixer configurations.
The important part is knowing how to activate the alternative source.
In OBS, audio sources can be managed through the Audio Mixer and Advanced Audio Properties.
Check the meters regularly, but don’t rely exclusively on visual indicators.
A source may show activity while delivering distorted, delayed, or incorrectly routed audio.
Listening through a monitoring device or external playback feed provides another layer of verification.
Protect Camera and Capture Sources
Capture cards can fail because of driver conflicts, loose connections, overheating, or incompatible video formats.
If your entire stream depends on one external capture device, its failure could remove your main video source.
Consider maintaining a simpler backup capture method when supported.
For example, a PC gamer might switch from a specialized capture workflow to a compatible direct game-capture source.
A creator using a dedicated camera could fall back to a secondary webcam.
Test every backup source before the broadcast.
A backup camera that hasn’t been configured correctly isn’t much better than having no backup at all.
Prepare for Power Interruptions
Power disruptions can affect multiple devices simultaneously.
A short outage might shut down the streaming computer, modem, router, network switch, and audio equipment.
An uninterruptible power supply, commonly called a UPS, can provide temporary battery power to selected devices.
The purpose isn’t necessarily to continue broadcasting for hours.
Instead, the UPS can help your equipment survive brief interruptions or provide enough time for a controlled shutdown.
Calculate the expected load and verify the battery runtime using the manufacturer’s specifications.
For essential productions, powering both the encoder and networking equipment may be more valuable than protecting only the computer.
Remember that a UPS doesn’t help if an upstream internet provider’s infrastructure also loses power.
5. Preserve Recordings, Settings, and Essential Production Assets
A livestream interruption doesn’t always mean losing the entire production.
If recordings and project configurations are protected, you may still be able to recover valuable content.
This is particularly important for tournaments, interviews, educational broadcasts, and sponsored events.
Record Locally While Broadcasting
Local recording creates another copy of your production independent of the live delivery platform.
If your internet connection fails, your computer may still continue recording gameplay and commentary.
However, local recording requires sufficient storage capacity and processing resources.
Test the performance impact before enabling high-quality recording during demanding games.
OBS supports multiple recording formats, including MKV and MP4.
According to its official Audio/Video Formats Guide, MKV is designed to remain recoverable even when a recording is interrupted unexpectedly.
Traditional MP4 and MOV recording configurations can be more vulnerable because they require proper file finalization.
Fragmented MP4 and MOV formats offer another interruption-resistant option when supported.
For many OBS users, recording to MKV and remuxing afterward is a practical approach.
Store Production Settings Safely
Streaming configurations may take hours to build.
Losing a complicated scene collection, audio routing configuration, or customized output profile can create unnecessary downtime.
OBS supports exporting Profiles and Scene Collections.
Save backup copies after major changes and keep them somewhere independent of your primary computer.
Remember that exporting configuration files doesn’t necessarily preserve every external asset.
Fonts, images, audio files, plugins, and media sources may need to be backed up seperately.
Test restoration on another system to confirm that the required dependencies remain available.
Also protect stream keys and account credentials instead of including them in publicly accessible backup folders.
Use Multiple Storage Locations
Local recordings protect against internet interruptions but not necessarily storage failures.
If everything is saved to one drive, a hardware problem could destroy your only copy.
A sensible approach combines local working storage with an additional independent backup destination.
For particularly valuable productions, off-site or cloud storage provides protection against failures affecting the entire local system.
Use backup scheduling that matches the importance of the content.
An occasional casual livestream may not justify immediate duplication, while a major esports tournament could require multiple recording paths.
The objective is preserving irreplaceable content without making storage management unnecessarily complicated.
6. Monitor Broadcast Health and Follow a Clear Recovery Procedure
Redundant equipment is only useful when someone can identify problems and activate the correct recovery method.
This requires monitoring, clear responsibilities, and practical incident-response procedures.
Monitor the Viewer Experience
A streaming application may report that everything is working while viewers experience buffering, frozen images, or missing sound.
Monitor both the local production system and the actual public broadcast.
OBS provides performance statistics related to rendering, encoding, and network delivery.
YouTube’s Live Control Room also includes stream-health indicators and error messages.
These tools help identify whether a problem originates from capture, encoding, transmission, or the playback environment.
A separate viewing device on an independent connection can reveal issues that aren’t obvious from the production computer.
However, viewer playback naturally introduces delay.
Account for that delay when comparing live production signals with audience playback.
Create an Emergency Response Checklist
Under pressure, even experienced production teams can overlook simple troubleshooting steps.
A written response procedure helps prevent random changes that make a problem worse.
A useful emergency checklist might follow this order:
- Identify the failure: Determine whether the issue affects video, audio, encoding, networking, or the platform.
- Check stream health: Review OBS statistics, platform alerts, and the external monitoring feed.
- Activate the backup: Switch to the appropriate secondary connection, audio source, encoder, or capture configuration.
- Verify recovery: Confirm that viewers receive stable video and audio again.
- Communicate appropriately: Give viewers a brief update through an available channel if the interruption is noticeable.
- Document the incident: Record what happened, how it was resolved, and what should change before the next broadcast.
Keep the procedure short enough to follow during a stressful live event.
For team productions, assign responsibility for each major recovery action.
One person might monitor stream health while another handles technical switching.
Clear roles reduce confusion and make incident response more predictable.
Use Graceful Degradation Instead of Immediate Shutdown
Sometimes the best response isn’t restoring the full production immediately.
Instead, keep the broadcast running with fewer features.
For example, if your animated overlays cause rendering problems, switch to a simpler scene.
If network bandwidth becomes unstable, reduce the output bitrate or resolution using a tested configuration.
If your main camera stops functioning, continue with audio and gameplay while troubleshooting.
This approach is called graceful degradation.
Rather than allowing one component failure to end the event, the system continues operating with reduced functionality.
For creators, that may be enough to preserve the audience experience until normal production can resume.
7. Test Your Redundancy Strategy and Improve It Over Time
A backup solution that has never been tested is only a theory.
Reliable streaming workflows require controlled failure simulations, performance measurements, and occasional maintanance.
The goal is discovering weaknesses before they interrupt an important livestream.
Run Realistic Failure Simulations
Begin with low-risk scenarios outside public broadcasts.
Disconnect the primary internet connection and observe whether the backup network activates.
Test whether OBS reconnects correctly and how the streaming platform handles the interruption.
Then simulate other problems.
Disable a camera source, disconnect a nonessential microphone, or close your primary encoding application during a controlled test.
Observe whether your recovery procedures actually work.
For potentially disruptive electrical tests, use safe simulation methods rather than creating hazardous power conditions.
Record the results and identify steps that require improvement.
Measure Recovery Time
Two useful reliability concepts are Recovery Time Objective (RTO) and Recovery Point Objective (RPO).
RTO describes how quickly a service should be restored following a failure.
RPO describes the maximum acceptable amount of lost data or content.
For example, a competitive tournament might aim to restore its broadcast within 30 seconds after certain equipment failures.
It might also aim to preserve recordings with no more than a few seconds of lost footage.
These are hypothetical planning targets, not universal industry standards.
A smaller creator may accept a recovery time of several minutes.
Your targets should reflect audience expectations, technical capability, and production costs.
Balance Reliability Against Budget
Redundancy introduces expenses through backup equipment, additional internet subscriptions, cloud infrastructure, storage, and maintenance.
More redundancy isn’t automatically better.
A complicated system can create new problems if nobody understands how to operate it.
Start with affordable improvements such as a backup microphone, exported OBS configurations, local recording, and a tested secondary internet option.
As your channel grows, consider dedicated encoders, professional network failover, or managed broadcast infrastructure.
Evaluate upgrades based on how much risk they actually reduce.
Spending money on a second expensive camera may be unnecessary if your biggest production problem is recurring internet instability.
Review Every Incident
After a production failure, document what happened without turning the review into a search for someone to blame.
Identify the triggering event, affected components, recovery actions, and total interruption time.
Look for recurring patterns.
If your backup network repeatedly struggles during evening broadcasts, investigate signal strength, congestion, or service limitations.
If encoder crashes happen after adding new plugins, test those components before future productions.
Regular reviews transform technical problems into useful operational lessons.
Over time, your streaming system becomes easier to troubleshoot, more predictable, and better prepared for unexpected situations.
Managing livestream production failures isn’t about preventing every technical problem. It’s about ensuring that unexpected issues don’t automatically bring your entire broadcast to a halt.
Reliable production starts with identifying critical failure points and creating practical alternatives for internet connectivity, encoding, audio, video capture, power, and recording.
Monitoring systems and clear recovery procedures help those backups work when they’re needed most.
Importantly, redundancy should match the scale and importance of your production. A smaller creator can achieve meaningful protection without investing in expensive broadcast infrastructure.
Start by reviewing your current setup and identifying its three most serious vulnerabilities. Build a recovery plan for each one, test your alternatives, and improve them after every incident.
The most professional livestream isn’t necessarily the one that never experiences problems. It’s the one that’s prepared to recover when those problems happen.